Clusters
Feature Overview
| Item | Content |
|---|---|
| Applicable Role | Model Provider and Model Consumer |
| Navigation Path | AI Infra(On-Prem) > Monitoring > Clusters |
| Page Route | /powerone/user-monitor/cluster |
| Managed Object | Configuration, status, and relationships on Clusters |
Beginner Explanation
Cluster statistics are like a capacity table for the user-visible resource pool. They help determine how much cluster capacity, node scale, and accelerator resources are still available in the current region for tasks.
Terms
| Term | Description |
|---|---|
| Cluster Name | Kubernetes cluster identifier that hosts instances, jobs, and resource scheduling. |
| Health Status | Overall cluster availability, usually determined by collection, node, and scheduling status together. |
| Total GPUs | Number of accelerators visible or included in statistics for the current cluster. |
Recommended Operation Order
Confirm prerequisites for Cluster resource trends, capacity, and health status within the user-visible scope, follow Main Operations, run Result Validation, and continue to the next page.
First-Time User Notes
Confirm that the task involves Configuration, status, and relationships on Clusters, and then follow the recommended order. If fields or state differ from expectations, check prerequisites before continuing downstream.
Prerequisites
- The current account can view cluster statistics in the target region.
- The operator has included related clusters in the user-side monitoring scope.
- Cluster monitoring data has been synchronized to the user-side page.
- The current account has permission to view resource watermarks or health status.
Page Description
Use this page to inspect cluster resource trends, capacity, and health state within the current user's scope.
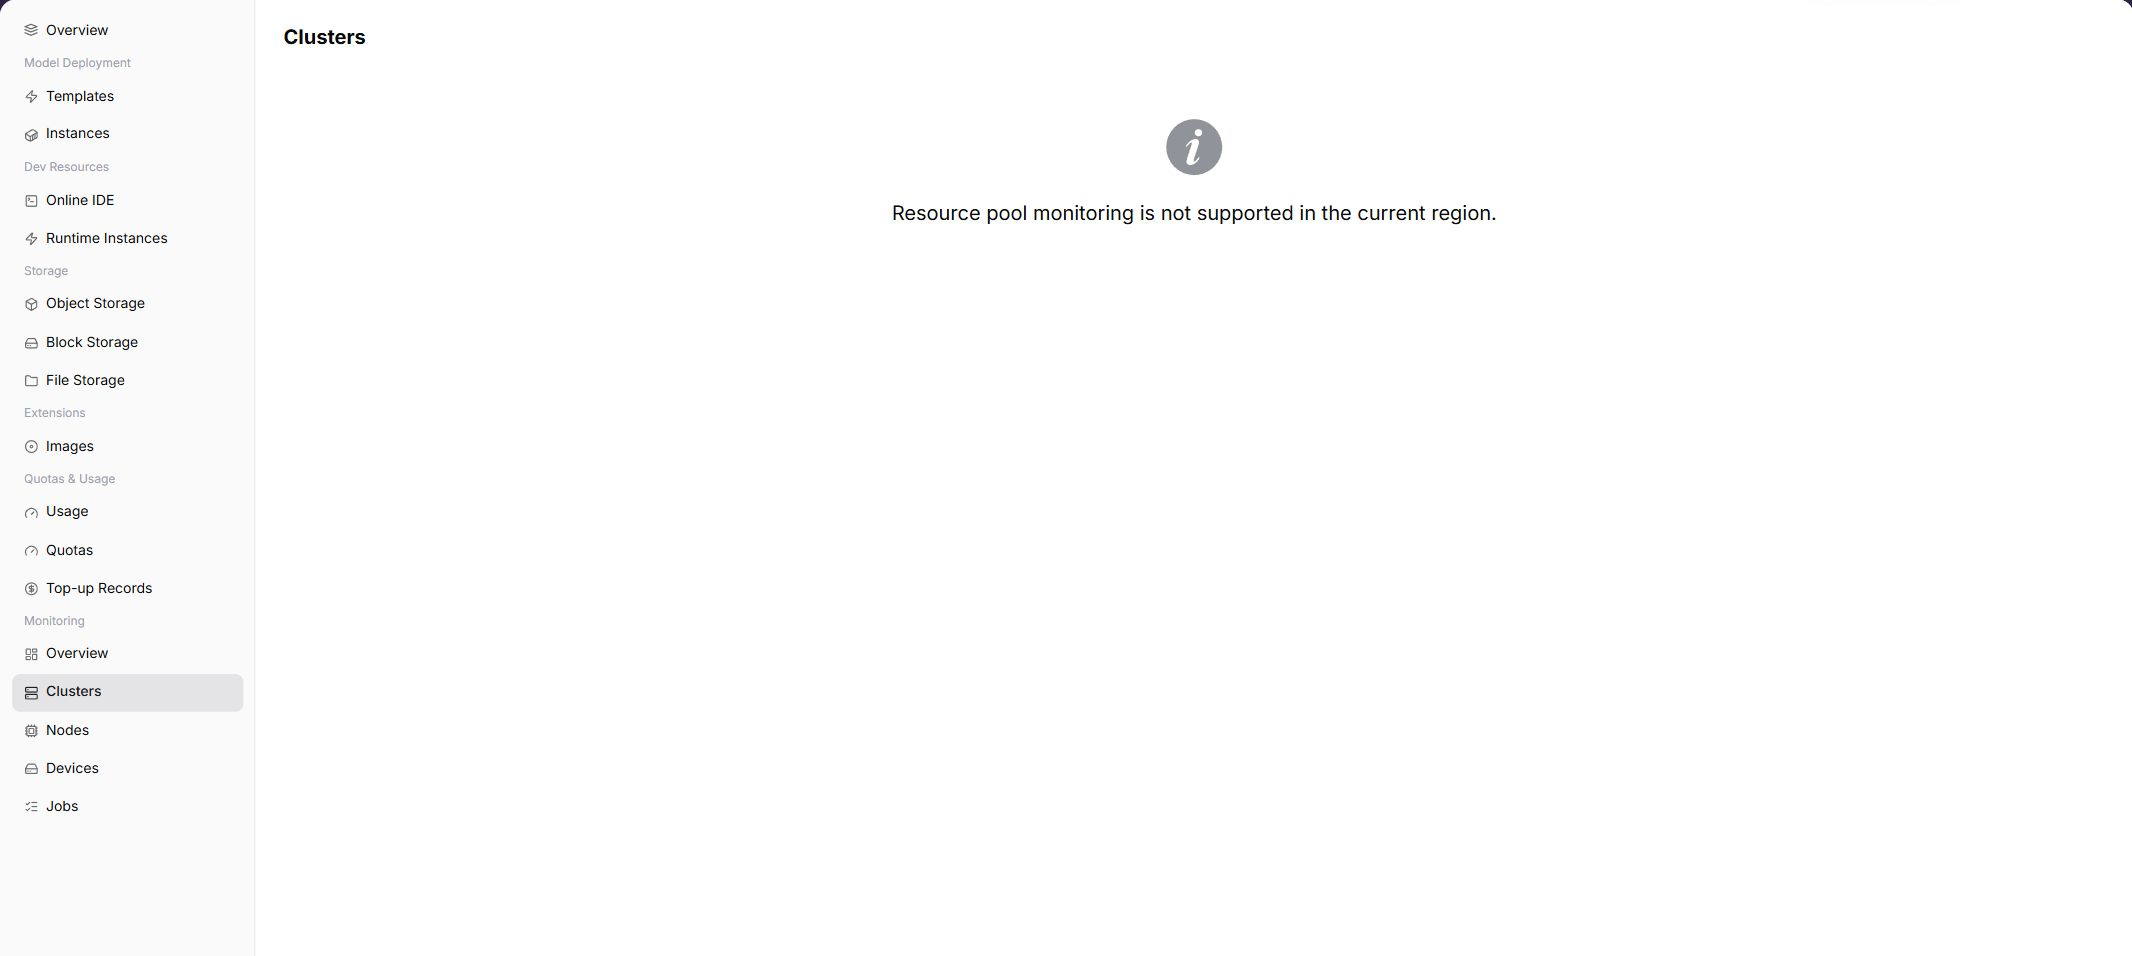
The page displays cluster statistics capability for the selected region. When the capability is opened, users can view metric trends, list data, or key status. When the capability is not opened, the page shows a capability prompt.
Expected Page Elements When Capability Is Open
| Page Element | Example | Description |
|---|---|---|
| Cluster List | prod-wuhan-gpu-1 | Displays clusters within the user-visible scope. |
| Cluster Watermark | GPU 12/32, CPU 60% | Determines whether capacity is tight. |
| Available Capacity | A100 remaining 4 cards | Determines whether it is suitable to continue submitting jobs. |
| Health Status | Available / Abnormal / Under maintenance | Determines whether the cluster is suitable for new instances. |
| Capacity Trend | Resource usage in the last 24 hours | Determines short-term resource pressure. |
Main Operations
View Cluster Statistics
- Go to
AI Infrastructure > On-Prem > Monitoring > Cluster Statistics. - Confirm the region and time range in the upper-right corner, and filter by cluster name or status.
- View the cluster list and operational status, and verify available capacity, CPU/GPU watermarks, and health status.
- If monitoring capability is not opened, return to the instance details page to view logs, events, and status.
Investigate Abnormal Cluster Metrics
- When cluster resource watermarks approach full capacity or enter maintenance status, record the cluster name and load level.
- Switch to
Node StatisticsorJob Monitoringto inspect individual node utilization and current queued jobs. - If persistent cluster capacity shortages prevent new instances from being created, contact the administrator to request quota adjustments or allocate alternative resource pools.
Key Focus When Capability Is Open
- Whether cluster health status is normal.
- Whether node count, total GPUs, and total CPUs match expectations.
- Whether resource watermarks are close to thresholds that affect new task creation.
Parameter Quick Reference
| Field Name | Required | Field Type | Example | Description |
|---|---|---|---|---|
| Cluster Name | Yes | Text | cluster-a | Locates the user-visible cluster object. |
| Region | Conditionally required | Drop-down | Central China Zone 1 | Limits the region to which the cluster belongs. |
| Node Count | System-generated | Number | 24 | Number of nodes included in statistics in the cluster. |
| Total GPUs | System-generated | Number | 96 | Total visible accelerators in the cluster. |
| Total CPUs | System-generated | Number | 1536 Core | Total CPU capacity of the cluster. |
| Health Status | System-generated | Status | Healthy | Shows whether the cluster is available, alerted, or collection abnormal. |
Pitfalls
- High cluster watermarks do not necessarily mean your task will fail. Also check target specification and quota.
- When cluster health is abnormal, do not repeatedly submit the same job. Confirm platform events first.
- Do not mix resources from different regions in the same judgment.
Troubleshooting Information to Prepare
When cluster data is abnormal, prepare the following information to distinguish cluster onboarding, resource watermark, and collection issues:
| Information | Example | Purpose |
|---|---|---|
| Cluster name | cluster-prod-a | Locates the target cluster. |
| Region / Availability zone | Wuhan / wuhan-1 | Confirms the resource ownership scope. |
| Node count | 32 | Determines whether cluster capacity matches the expectation. |
| Health state | Abnormal / High watermark / No data | Distinguishes capacity issues from collection issues. |
| Related job time | 2026-07-13 10:00 | Aligns job submission with the monitoring curve. |
Result Validation
| Check Item | Success Signal | If Abnormal |
|---|---|---|
| Page load | Clusters charts or lists are visible | Check monitoring permission and whether collection is available in the selected region |
| Scope | Time range, region, and object count match the investigation | Clear filters and restore them one at a time to avoid mixed scopes |
| Freshness | Update time is within the expected collection interval | Check collection interval, connection, and alerts in system or monitoring configuration |
| Correlation | An abnormal metric can be linked to a cluster, node, device, or job | Keep the same time range and cross-check adjacent monitoring pages and object details |
FAQ
No Data on Clusters
Symptom:
The page opens, but charts or lists are empty.
Possible Causes:
- No job ran in the selected time.
- collection is unavailable in the region.
- the role lacks metric permission.
Solution:
- Expand the time range and reset filters
- verify regional monitoring capability
- compare an adjacent monitoring page.
Clusters Is Not Updating
Symptom:
The data does not change for an extended period.
Possible Causes:
- The next collection cycle has not arrived.
- the collector is abnormal.
- the page is cached.
Solution:
- Check update time
- inspect collector status and alerts
- refresh with the same time range.
Clusters Differs from Adjacent Pages
Symptom:
The same object has different values on two monitoring pages.
Possible Causes:
- Aggregation granularity differs.
- time range or time zone differs.
- filters target different objects.
Solution:
- Align time range and time zone
- verify aggregation scope
- clear and restore filters one at a time.
Unable to Locate Target Object in Related Monitoring
Symptom:
The metric or details entry does not lead to the expected object.
Possible Causes:
- The object ended or was removed.
- the role cannot see it.
- relationship identifiers differ.
Solution:
- Record object and time
- check its list state
- ask the Operator to verify visibility.
A Spike Cannot Be Reproduced
Symptom:
A spike was recorded, but current details are normal.
Possible Causes:
- The spike was brief.
- sampling is coarse.
- the job has ended.
Solution:
- Lock the spike interval
- compare job and node events
- retain a sanitized screenshot and object identifier.
Notes
- Do not expose real cluster names, internal domains, or node IPs in screenshots.
- Cluster health status and single instance status may not be synchronized. Judge together with logs and events.
- When capacity is insufficient, confirm the target specification first instead of looking only at total cluster watermarks.
Next Steps
- Go to node statistics to check whether a small number of nodes caused the cluster exception.
- Go to device monitoring to confirm whether GPU/NPU resources are sufficient.
- Before creating tasks, judge together with resource quotas and specification availability.